Picture a finance team on the last day of the month. Invoices arrive as PDFs, scans, photos and email attachments. Someone opens each one, types the supplier name, amount and PO number into the ERP, then drags the file into a folder named something like “Final_v3_USE THIS.” Meanwhile, a manager across the hall spends twenty minutes hunting for a contract that everyone agrees exists.
Nothing here is dramatic. That is the problem. The cost of unmanaged documents shows up as slow approvals, repeated work, missed renewal dates, audit stress and employees who quietly stop trusting the filing system.
This guide explains how to enable AI in document management through content preparation, tool selection, a controlled pilot, secure retrieval and measurable rollout. Start with one document problem and keep people accountable for important decisions.
A small pilot may be possible without a data science team, especially with managed services. You still need a business owner, an administrator, security input and reviewers who understand the documents.
Reliable document AI depends on content ownership, appropriate access and ongoing evaluation. Good governance improves the conditions for useful results; it does not guarantee accuracy.
Quick Answer: How to Enable AI in Document Management
To enable AI in document management, start with one high-volume document type, clean up permissions and metadata, choose a platform-native or dedicated AI tool, pilot it with human review, connect it to your workflows, and track accuracy and time saved before scaling across departments.
What Is AI Enablement in Document Management
AI enablement adds capabilities to capture, classify, search, summarize and route documents. Your document management system remains the authoritative repository unless a deliberate migration is part of the project.
A chatbot alone does not establish records governance. Retention, access control, versioning and audit requirements must be designed and tested across the full workflow.
In practice, AI enablement usually combines five capabilities:
- Capture: OCR and layout analysis turn scans and PDFs into machine-readable text and tables.
- Classification: Models identify document type, department, sensitivity and retention class.
- Extraction: Services identify fields such as invoice numbers, contract dates or employee IDs. Confidence scores are available for some models and fields; validate their usefulness on your own documents.
- Search and Q&A: Semantic search and retrieval-augmented generation (RAG) let people ask questions and get answers with citations.
- Automation: Content-based triggers route documents, start approvals and update other systems.
Treat “AI in document management” as a pipeline, not a product. Capture, classify, extract, store, retrieve, and govern are separate steps, and each can be improved independently.
Illustrative example: A procurement workflow identifies a supplier contract and proposes its counterparty and renewal date. A reviewer checks those values and approves any retention label or reminder before it takes effect.
Why Enable AI in Document Management
Documents contain obligations, decisions, and working knowledge. AI can help when repeated searching, retyping or routing consumes staff time, provided accuracy and controls are measured.
Why now:
- Modern document services can combine OCR, layout analysis and learned extraction. Performance varies by model, language, layout and scan quality; evaluate difficult examples before choosing a service.
- AI capabilities are available in many business platforms, but eligibility, additional licenses, usage charges and administrative configuration vary.
- Records, privacy and security obligations depend on the organization, document type and jurisdiction. Identify applicable requirements before selecting processing services.
When AI is a good idea:
- You process repeatable document types in volume (invoices, forms, onboarding packets, claims).
- Staff lose real time searching or retyping.
- Compliance or audit requests are painful to answer.
When to wait:
- Permissions are badly out of control and nobody owns them.
- You have no agreed taxonomy or retention rules.
- Leadership wants “AI” but cannot name a specific document problem.
Starting with a tool demo instead of a document problem. Pick the pain first (slow invoice approval, unfindable contracts), then choose technology that fits it.
Benefits of AI in Document Management
Benefits are real, but they depend on use case and execution. Measure your own baseline rather than relying on vendor claims.
| Potential benefit | How to validate it |
| Faster retrieval | Measure against a manual baseline; verify quality and review effort. |
| Less manual data entry | Measure against a manual baseline; verify quality and review effort. |
| Better consistency | Measure against a manual baseline; verify quality and review effort. |
| Shorter cycle times | Measure against a manual baseline; verify quality and review effort. |
| Lower compliance exposure | Measure against a manual baseline; verify quality and review effort. |
| Knowledge reuse | Measure against a manual baseline; verify quality and review effort. |
| Fewer errors | Measure against a manual baseline; verify quality and review effort. |
| Benefit | Matching challenge to plan for |
| Faster retrieval | Over-shared files can surface to the wrong people if permissions are loose |
| Less data entry | Extraction errors on poor scans or unusual layouts |
| Automated classification | Misclassification affecting retention or legal hold |
| Cited Q&A | Wrong or outdated answers if the source library is not curated |
| Cost savings | Licensing, integration and review effort are real costs |
Every benefit has a matching risk. Good implementation plans for both from day one.
Where AI Can Be Implemented
AI fits best where documents are frequent, similar to each other and tied to a clear next action. The table below maps common use cases by department.
| Department | Documents and practical use |
| Finance and AP | Invoices, receipts, purchase orders. Capture, extraction, three-way matching support. |
| Procurement and Legal | Contracts, NDAs, amendments. Clause detection, renewal dates, comparison, summaries. |
| HR | Resumes, onboarding packets, policies. Classification, filing, policy Q&A. |
| Operations and Quality | SOPs, work instructions, inspection reports. Version control, search, change summaries. |
| Customer service | Manuals, tickets, knowledge articles. Cited answers from approved content. |
| Compliance and Records | Policies, regulated records. Retention labeling, sensitive data discovery. |
| Engineering and Construction | Drawings, submittals, RFIs. Indexing, metadata extraction, search. |
| Healthcare administration | Referrals, forms, claims. Intake classification and extraction. |
| Public sector | Case files, public records requests. Search, redaction support, retention. |
Score each candidate use case from 1 to 5 on volume, manual effort, document consistency and business value. Subtract points for data sensitivity, integration effort and regulatory risk. Begin with the highest net score.
Illustrative example: An HR team may choose a curated policy library before personnel files. Onboarding packets can contain identity, financial and health information, so they require a privacy review rather than an assumption of low risk.
Step by Step AI Enablement Roadmap
The eight steps below define owners, deliverables and exit tests. A 90-day schedule later in this guide is an illustrative planning framework, not a delivery commitment. Procurement, cleanup and integration can extend the work.
Step 1 Assess what you actually have
What: A plain inventory of where documents live (shared drives, email, SharePoint, Google Drive, Box, legacy DMS, paper rooms), what types they are, and who can access them.
Why: You cannot prioritize or secure what you cannot see.
How: Export folder structures and permission reports. Interview three or four heavy document users. Note scan quality, languages and file formats.
Who: IT, records management, plus one business owner per department.
Audit permissions before connecting AI. Microsoft 365 Copilot uses existing access rights, which can make overshared content easier to discover. A custom system must explicitly enforce equivalent controls.
Step 2 Prioritize one use case and define success
Choose a single document family. Write down the baseline: how long it takes today, how many people touch it, how often errors occur. Without a baseline you cannot prove improvement later.
One document type. One owner. One baseline metric. One target. One review date.
Step 3 Prepare content and governance
This step decides success more than any tool choice.
- Remove obvious duplicates and obsolete versions.
- Fix inherited and open permissions on target libraries.
- Define a small metadata schema (for example: document type, department, counterparty, effective date, retention class).
- Confirm retention rules with legal or records management.
- Write a one-page AI use policy: what data may be processed, which tools are approved, who reviews outputs.
- Improve scan quality standards for paper intake.
Keep the first metadata schema small and relevant to the workflow. Add fields only when they support retrieval, validation or a defined records requirement.
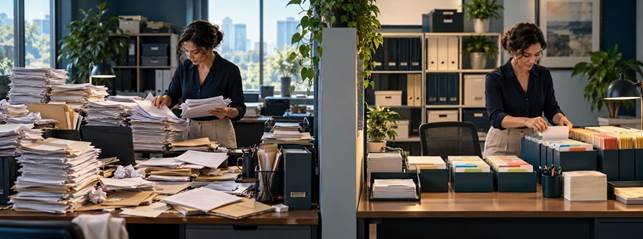
Organize documents and clarify ownership before connecting AI.
Step 4 Select your technology path
There are three practical paths, covered in detail in the technologies and tools sections below:
- Platform-native AI inside the system you already use.
- Dedicated intelligent document processing (IDP) added to your DMS.
- Custom RAG and LLM build on your own cloud stack.
Run a proof of concept using your own difficult documents, not the vendor’s polished samples.
Step 5 Pilot with humans in the loop
Build a labeled test set (documents with known correct answers). Measure accuracy before go-live. Route low-confidence results to a review queue. Never let AI alone make irreversible decisions such as deletion or legal hold release.
Step 6 Integrate with the systems that matter
Extraction has little value until data lands where work happens: ERP, CRM, HRIS, case management or ticketing. Use native connectors or APIs, and log every automated action.
Step 7 Train people and roll out in waves
Name a champion in each department. Teach people what AI is good at, where it can be wrong, and how to flag errors. Expand one team at a time.
Step 8 Monitor, audit and improve
Review quality frequently during the pilot and after any change. Set a risk-based schedule for production audits, and re-test when models, prompts, document formats or permissions change.
AI Technologies Used in Document Management
Not every AI technology does the same job. Knowing the difference stops you buying a chatbot when you needed an extraction engine.
Compare specialist extraction models and general language models on the same held-out documents. Structured outputs, validation, review effort and cost matter more than a broad claim that one technology always performs better.
Realistic example (illustrative): A company uses an IDP service to extract invoice fields, then an LLM to summarize long supplier agreements. Each tool does the job it is best at.
Platform-native AI suits teams whose existing repository already has suitable AI features. Confirm licensing, governance controls and deployment effort before assuming it will be the simplest option.
Dedicated intelligent document processing combines capture, classification and extraction. Google Document AI and Amazon Textract are examples to evaluate on supported document types, languages and validation needs.
Microsoft Document Intelligence supports text, structure and field extraction. A custom search or RAG system adds retrieval and answer generation, but its builders must implement authorization, logging and evaluation.
| Path | What it means | Effort | Flexibility | Best when |
| 1. Platform-native AI | Turn on AI inside Microsoft 365, Google Workspace, Box or your current DMS | Low | Medium | You already standardize on one platform and want fast, governed wins |
| 2. Dedicated IDP added to your DMS | Add a specialist extraction engine and connect it | Medium | Medium to high | Document accuracy matters (invoices, claims, KYC) and volume is high |
| 3. Custom RAG or LLM build | Assemble OCR, vector search, LLM and workflow yourself on a cloud stack | High | Very high | You have engineering skills and unusual requirements |
Features, editions and pricing change often. Confirm against official documentation before buying.
Before you sign anything, ask each vendor three questions: Is my data used to train models? Where is it processed and stored? How are existing permissions enforced in AI answers? Get the answers in writing.
A general-purpose chat interface does not automatically provide your required records controls. Verify retention, auditability, access enforcement and contractual data handling for the exact service and integration.
Implementation Process Hands-On Detail
The roadmap told you the sequence. Here is what the technical and operational work looks like inside the pilot.
1. Build the labeled test set
Collect representative documents, including poor scans, handwriting, supported languages and uncommon layouts. Label the correct outputs. Separate configuration examples from a held-out test set to avoid optimistic results. A few hundred documents may help an initial pilot, but sample size should reflect variety, rare errors and business risk.
2. Design the capture pipeline
Define approved intake channels, supported formats and scan-quality requirements. Preserve originals, capture provenance, scan uploads for malware and quarantine unsupported or damaged files. Input quality is one important source of extraction errors.
3. Configure classification
Define document classes and what makes each distinct. Start with prebuilt models where they exist. Measure precision and recall per class, not just overall accuracy, since one weak class can hide behind a strong average.
4. Configure extraction and validation
Define required fields and business checks, such as matching totals, valid dates and supplier IDs. Choose field-specific confidence thresholds using held-out results and error costs. Scores are not guarantees; review critical fields even when confidence is high.
5. Set up the human review queue
Reviewers should see the document, the extracted value and the confidence side by side. Capture their corrections. Those corrections become your improvement data.
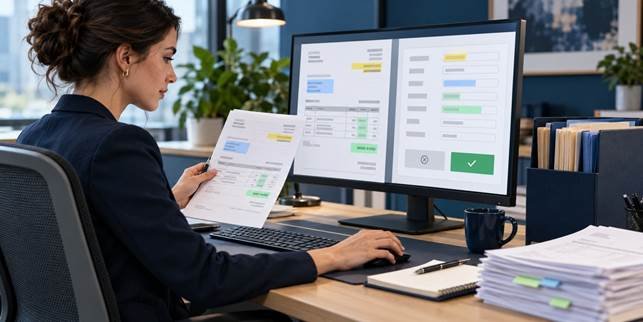
Check extracted values before approving downstream actions.
6. If you add search or Q&A, control retrieval
- Index only approved, current libraries.
- Enforce permission trimming so answers draw only from documents the asker may open.
- Require source links and test whether each cited passage actually supports the answer. Citations alone do not prove correctness.
- Treat document text as untrusted input. Test for prompt injection in uploaded documents, and prevent retrieved text from granting permissions or authorizing actions.
Pointing an AI assistant at an entire shared drive on day one. Start with one curated library and expand once answers prove reliable.
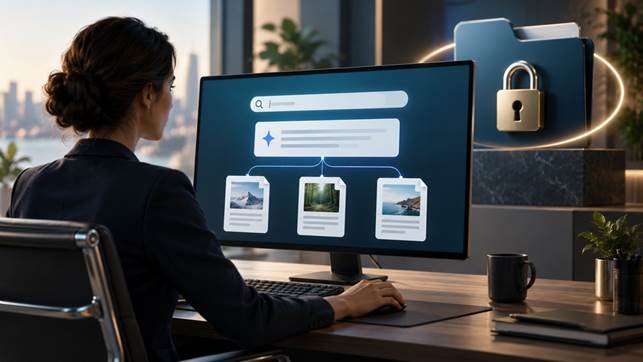
Limit retrieval to authorized sources and verify supporting passages.
7. Integrate and log
Connect outputs to the downstream system. Log what the AI did, with what confidence, and who approved exceptions. This audit trail is what compliance teams will ask for.
8. Run the pilot and decide
Compare pilot metrics to the baseline from Phase 2. Decide whether to scale, adjust or stop. Stopping is a legitimate result if the numbers do not justify the effort.
Implementation timeline view
| Period | Focus | Exit test |
| Days 1 to 30 | Assess, prioritize, start cleanup and policy | Pilot scope signed off |
| Days 31 to 60 | Finish preparation, run proof of concept, build test set | Tool chosen on evidence |
| Days 61 to 90 | Configure pilot, human review, measure | Accuracy and time results vs. baseline |
| After day 90 | Integrate, train, scale in waves | Stable KPIs across first department |
Who does what
| Department | Responsibility |
| Executive sponsor | Funding, priorities, removes blockers |
| Business process owner | Defines success, accepts outputs |
| IT and cloud admin | Architecture, integrations, access, monitoring |
| Records and information governance | Taxonomy, retention, classification rules |
| Information security and privacy | Risk review, vendor assessment, DLP |
| Legal and compliance | Regulatory mapping, policy approval |
| Subject-matter reviewers | Validate outputs, supply corrections |
| Change and training lead | Communication, training, adoption tracking |
Common Challenges
- Messy content and permissions. Duplicates, old versions and over-shared folders undermine search and trust.
- Accuracy gaps. Poor scans, mixed languages, handwriting and unusual layouts lower extraction quality.
- Hallucination. Generative models can produce fluent but wrong answers if not grounded in approved sources.
- Security and privacy worries. Leaders fear data leaving the organization or being used for training.
- Applicable requirements depend on location, data and use case. Have responsible specialists assess privacy, records and sector obligations; do not assume that any AI feature establishes compliance.
- Integration friction. Legacy systems may lack modern APIs.
- User resistance. People worry about job impact or distrust the output.
- Cost creep. Usage-based pricing and extra licenses add up without monitoring.
- Model drift. Accuracy can slip as document formats and business language change.
Solutions
| Risk | Practical mitigation |
| Over-shared files surfaced by AI search | Run a permission audit and clean up before enabling AI search or assistants |
| Hallucinated answers | Use RAG with citations, restrict to approved sources, require human review for high-stakes use |
| Misclassification affecting retention or legal hold | Use confidence thresholds, sample audits, and never delete automatically on an AI judgment alone |
| Poor scan or data quality | Set capture standards, add preprocessing, check language support |
| Low adoption | Pick simple first use cases, name champions, train early, publish quick wins |
| Vendor lock-in and cost creep | Keep metadata exportable, use open formats, monitor usage, review contracts |
| Model drift | Re-test on a fresh labeled sample on a fixed schedule |
| Vendor data handling | Review training use, retention, subprocessors, regions and access terms; private networking alone does not settle these issues. |
Map relevant privacy, security and records obligations to the actual workflow. AI-specific rules may also apply. Verify current requirements using official sources and qualified advice where needed.
Best Practices
- Start narrow. One document type, one department, one measurable goal.
- Fix governance before automation. Permissions, taxonomy, retention and an AI use policy come first.
- Test on your worst documents. Vendor demos use clean samples; your reality does not.
- Keep humans in the loop for anything legally or financially significant.
- Set and publish confidence thresholds. People trust a system that explains its limits.
- Log everything. Every AI action should be traceable.
- Use the NIST AI Risk Management Framework to structure governance, evaluation and monitoring. Select any additional records or security standards according to your organization’s requirements.
- Version your rules and prompts like code, so changes can be reviewed and rolled back.
- Measure against a baseline, not against hope.
- Communicate early. Explain what changes for each role and what does not.
Appoint a named owner for AI document accuracy. Shared responsibility often means no responsibility.
Treat reviewer corrections as the most valuable data you will collect. A simple log of what was wrong and why will guide every later improvement.
Illustrative document workflows
The scenarios below are illustrative workflows, not customer case studies or reported results.
Example 1 Accounts payable invoice intake
Before: Staff open emailed invoices, type fields into the ERP, and chase approvers by email. After: An intake mailbox feeds an IDP engine. Fields are extracted, checked against purchase orders and supplier master data, and clean invoices flow to approval. Exceptions land in a review queue.
Example 2 Contract renewal visibility
Legal staff upload contracts to a governed library. AI proposes the counterparty, term and notice period, with links to source clauses. A qualified reviewer checks extracted obligations and date calculations before reminders or downstream actions are approved.
Example 3 Policy Q&A for employees
HR curates one library of current policies. A RAG assistant answers questions with citations and links to the source. If no approved source supports an answer, it says so and routes the question to HR.
For sector context, see our guide to AI implementation in banking, where document workflows sit within a broader governance program.
Cost vs. expected benefit
| Cost area | What to budget for | Benefit area it should return |
| Licenses and usage | AI add-ons, API or per-page fees | Hours saved on entry and search |
| Preparation | Cleanup, taxonomy, permissions work | Lower risk and better AI accuracy |
| Integration | Connectors, developer or partner time | Straight-through processing |
| Review effort | Staff time in the pilot | Higher accuracy and trust |
| Training and change | Sessions, champions, documentation | Adoption and sustained use |
| Governance | Policy, audits, monitoring | Compliance confidence |
How to measure success KPIs
| KPI | How to measure | Baseline to capture first |
| Straight-through processing rate | Documents completed with no human touch divided by total | Current manual share |
| Extraction accuracy | Correct extracted fields divided by evaluated fields; report critical fields separately and audit auto-accepted results. | Manual error rate |
| Classification accuracy | Correct labels on a labeled sample, per class | Existing misfiling rate |
| Time to find a document | Timed tasks or search analytics | Current average search time |
| Cycle time | Receipt to completion (for example invoice to approval) | Current average |
| Cost per document | Total processing cost divided by volume | Current cost |
| Exception rate | Items sent to review divided by total | Not applicable at start |
| User satisfaction | Short survey and feedback log | Pre-launch survey |
If you did not capture a baseline before the pilot, you cannot honestly claim improvement afterward. Measure first.
Implementation Checklist
AI readiness
- ☐ Named executive sponsor and business owner
- ☐ One prioritized use case with a baseline metric
- ☐ Inventory of repositories, volumes and document types
- ☐ Permission audit completed on target libraries
- ☐ Metadata schema (5 to 8 fields) agreed
- ☐ Retention rules confirmed with legal or records
- ☐ One-page AI use policy approved
Technology and security
- ☐ Path chosen (platform-native, dedicated IDP, or custom)
- ☐ Vendor data handling terms reviewed in writing
- ☐ SSO, DLP and encryption confirmed
- ☐ Proof of concept run on your real documents
- ☐ Logging and audit trail enabled
Pilot and rollout
- ☐ Labeled test set built
- ☐ Confidence thresholds set
- ☐ Human review queue staffed
- ☐ Integration tested end to end
- ☐ Training delivered; champions named
- ☐ Monthly accuracy review scheduled
If you can only do five things this month: audit permissions, pick one document type, capture a baseline, choose a platform-native pilot, and write the AI use policy.
Frequently Asked Questions
Can small businesses use AI for document management? Yes. Start with one workflow and check whether the current platform offers suitable AI capabilities. Availability, licenses and usage fees vary, and additional setup may be required.
2. How accurate is AI document extraction? It varies by document type, scan quality and tool. Clean, standard documents perform best. Always measure on your own sample rather than trusting a headline figure.
3. Should AI be allowed to delete or archive documents on its own? No, not on AI judgment alone. Use AI to recommend retention labels, and keep human or rule-based approval for deletion and legal holds.
4. What is the difference between OCR and IDP? OCR reads text from images. IDP adds layout understanding, classification, field extraction and validation on top of it.
Is RAG the same as fine-tuning? No. RAG retrieves source material at question time; fine-tuning adjusts model parameters. RAG can support current sources, but permissions and updates still require explicit engineering and testing.
6. Do I need a vector database? Not always. Platform-native tools handle indexing for you. A vector database matters mainly when you build a custom search or RAG system.
7. How do I stop AI from showing people documents they should not see? Audit and fix permissions first, then use tools that enforce security trimming so answers draw only from files the user can already open.
8. Can AI handle scanned or handwritten documents? It can for many cases, but accuracy drops with poor scans and handwriting. Improve capture quality and route low-confidence results to review.
What skills does the team need? A business owner, an administrator, records expertise, security input and reviewers. Managed tools can reduce development work; integrations may still require a developer or implementation partner.
How often should the system be re-tested? Review results frequently during a pilot, choose a risk-based production cadence, and re-test after changes to documents, models, prompts, permissions or integrations.
Does AI replace records managers? AI can assist with repetitive tasks, but people still define records policies, assess exceptions and oversee compliance. Staffing effects depend on the organization.
12. What should I ask vendors about data privacy? Whether your data trains their models, where it is processed and stored, how long it is retained, how permissions are enforced and what audit logs you receive.
Conclusion
Learning how to enable AI in document management comes down to disciplined sequencing. Know what you have, choose one valuable use case, clean up the basics, pick a technology path that fits your platform and skills, pilot with humans reviewing, integrate with the systems where work happens, and measure honestly.
The organizations that get lasting value are not the ones with the most advanced model. They are the ones with tidy permissions, clear ownership and a feedback loop that keeps accuracy high over time.
Start small, prove it with numbers, and expand with confidence.
Action Plan
| Timeframe | Action |
| This week | Name an owner. List your three most painful document problems. Capture baseline times. |
| Next 30 days | Audit permissions on one library. Draft metadata schema and AI use policy. Score use cases. |
| Days 31 to 60 | Shortlist tools. Run a proof of concept on your own documents. Build the labeled test set. |
| Days 61 to 90 | Run the pilot with human review. Compare to baseline. Decide: scale, adjust or stop. |
| After 90 days | Integrate, train, expand in waves, and schedule quarterly accuracy audits. |